When you take the function
$$f(x, y) = 3x^2 + 3y^2 + 2xy$$
and start gradient descent at \(x_0 = (6, 6)\) with learning rate \(\eta = \frac{1}{2}\) it diverges.
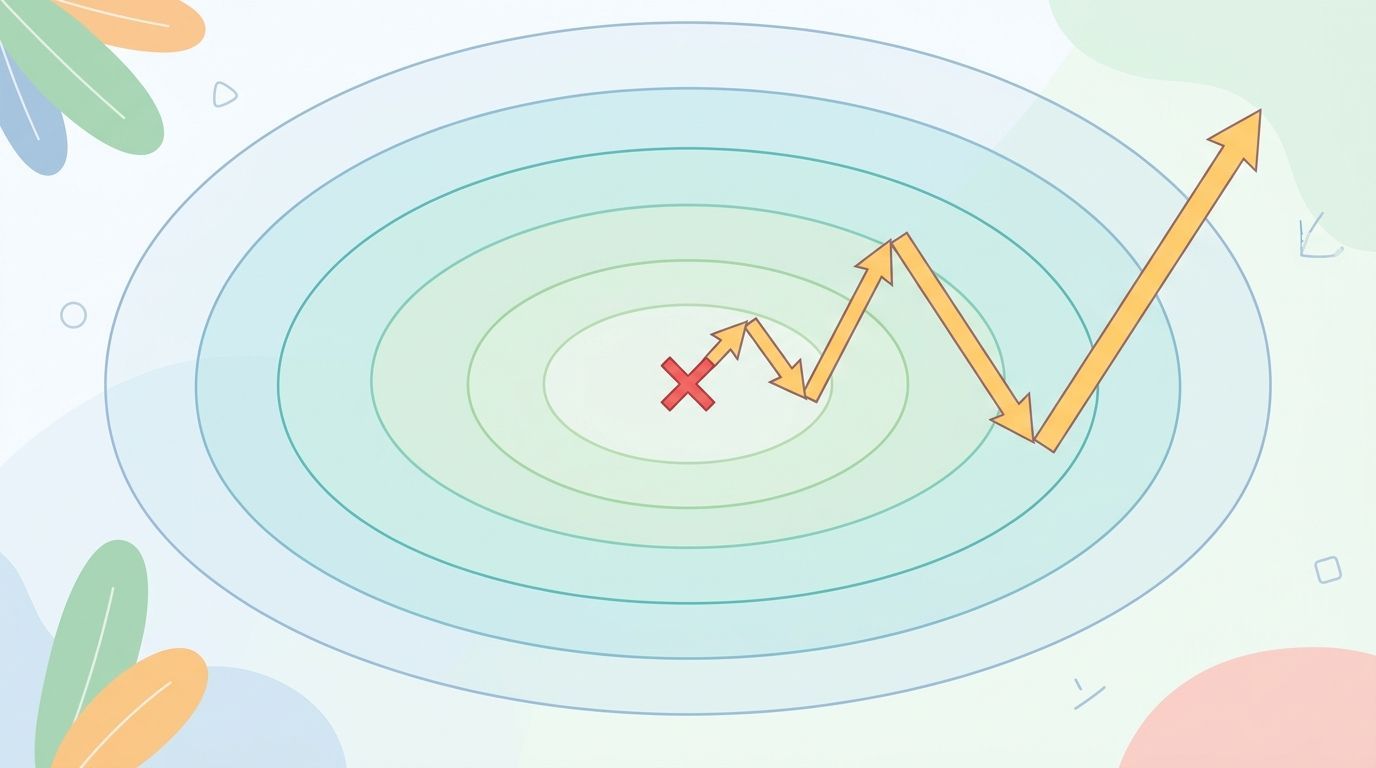
Gradient descent
Gradient descent is an optimization rule which starts at a point \(x_0\) and then applies the update rule
$$x_{k+1} = x_k + \eta d_k(x_k)$$
where \(\eta\) is the step length (learning rate) and \(d_k\) is the direction.
The direction is
$$d_k(x_k) = - \nabla f(x_k)$$
Example
$$\nabla f(x, y) = \begin{pmatrix}6x + 2y\\6y + 2x\end{pmatrix}$$
\begin{align}
x_0 &= (6, 6) & \eta d_k(6, 6) &= (-24, -24)\\
x_1 &= (-18, -18) & \eta d_k(-18, -18) &= (72, 72)\\
x_2 &= (54, 54) & \eta d_k(54, 54) &= (-216, -216)\\
x_3 &= (-162, -162) & \eta d_k(-162, -162) &= (648, 648)
\end{align}
In general:
\begin{align}
x_n &= (x_{n-1} - 8 \cdot \frac{1}{2} \cdot x_{n-1}, x_{n-1} - 8 \cdot \frac{1}{2} \cdot x_{n-1})\\
x_n &= (-3x_{n-1}, -3x_{n-1})
\end{align}
In general, \(x_n = (1 - 8\eta) \cdot x_{n-1}\). You can clearly see that any learning rate \(\eta > \frac{1}{4}\) will diverge (with \(\eta = \frac{1}{4}\) it jumps back and forth between \((6, 6)\) and \((-6, -6)\)). For this example, the learning rate \(\eta = \frac{1}{8}\) would find the solution in one step and any \(\eta < \frac{1}{4}\) will converge to the global optimum.